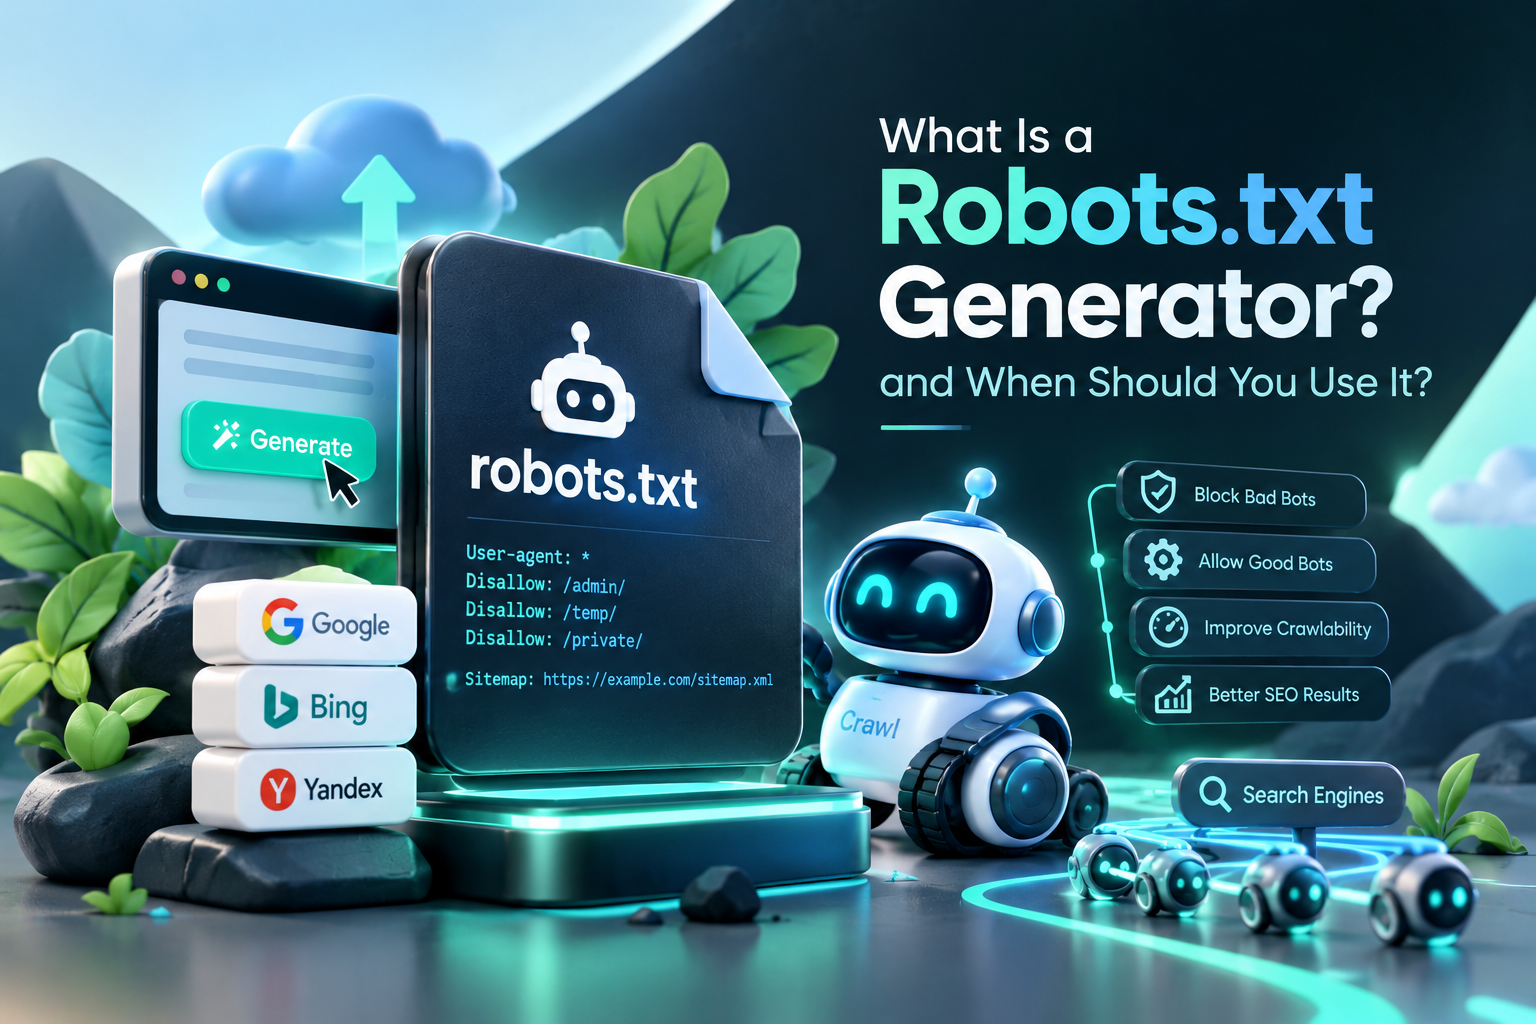

Search engine optimization (SEO) involves several technical processes that help search engines discover, crawl, and understand website content. While keyword research, high-quality content, backlinks, and on-page optimization receive significant attention, technical SEO is equally important for improving website performance in search results. One essential technical SEO element is a robots.txt generator, which helps website owners create a robots.txt file to guide search engine crawlers about which areas of a website they are allowed or disallowed to crawl.
A robots.txt generator is a useful SEO tool that helps website owners, bloggers, digital marketers, and developers create this file without writing every directive manually. It simplifies the process of managing crawler access and reduces the likelihood of common formatting mistakes. Whether you operate a small blog, a WordPress website, an e-commerce store, or a growing B2B SaaS platform, understanding how robots.txt works can help you maintain a more organized technical SEO strategy.
In this guide, you will learn what a robots.txt generator is, how it works, when you should use it, which directives matter most, and how to create and test a robots.txt file correctly.
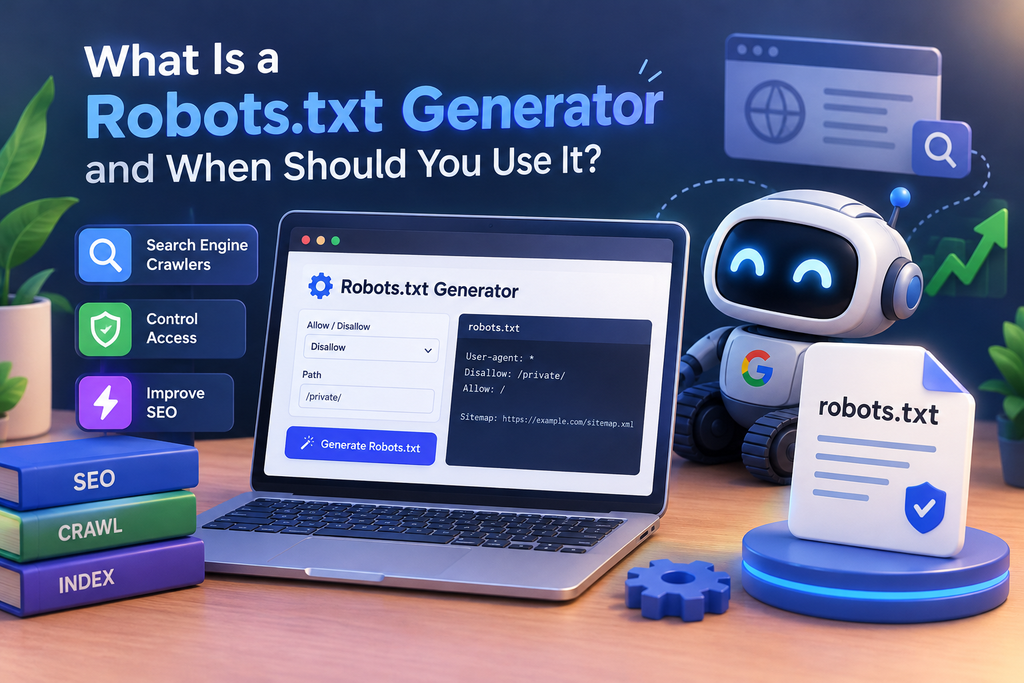
What Is a Robots.txt Generator?
A robots.txt generator is a web-based tool or software feature that creates a robots.txt file based on the instructions you provide. Instead of manually writing the file from scratch, you can use the generator to specify which sections of your website search engine crawlers should be allowed or discouraged from accessing.
The generated file contains directives that communicate crawling preferences to participating web crawlers. These instructions are usually written in plain text and follow a specific syntax.
For example, a basic robots.txt file might look like this:
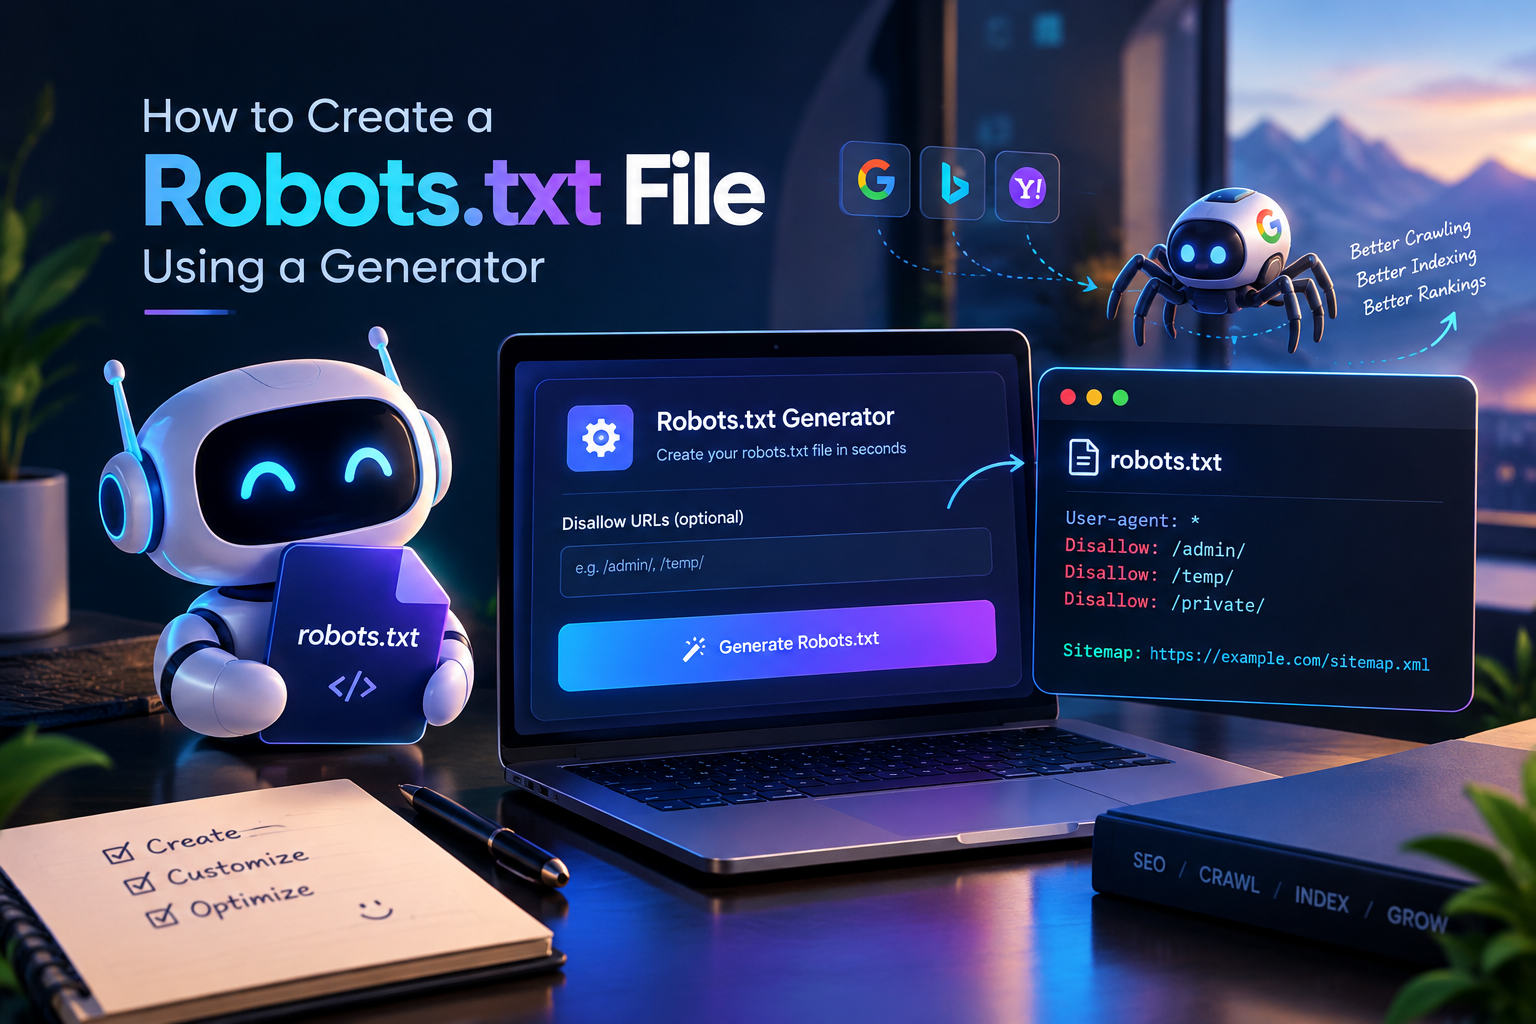
User-agent: *
Disallow: /admin/
Allow: /

Sitemap: https://example.com/sitemap.xml
In this example, User-agent: * applies the following rules to all matching crawlers. The Disallow directive asks crawlers not to crawl URLs under the /admin/ path, while Allow explicitly permits crawling of the website’s root path. The sitemap line identifies the location of the XML sitemap.
The example is illustrative, and actual rules should be adjusted to match the website’s structure. A robots.txt generator makes it easier to create these instructions, but the website owner must still confirm that the resulting rules are appropriate.
It is also important to understand that robots.txt is primarily a crawling control mechanism. It is not a reliable method for keeping private information secret, protecting restricted pages, or guaranteeing that a URL will not appear in search results.
How Does a Robots.txt Generator Work?
A robots.txt generator works by converting your selected crawling preferences into correctly structured text directives. Most tools provide a straightforward interface where you can enter paths, choose crawler rules, and specify your sitemap URL.
The general process includes the following steps.
1. Enter Your Website Information
Start by identifying your website’s domain and the paths you want to manage. Some generators allow you to specify a sitemap URL, select a user-agent, or choose predefined settings for common website configurations.
For example, a WordPress website may have administrative paths that should not be crawled, while a large e-commerce website may contain numerous internal search and filtering URLs.
2. Choose Crawling Rules
Next, decide which paths should be allowed or disallowed for crawling. A generator may provide fields for entering directories, files, or URL patterns.
For example, you might want to discourage crawling of a specific internal search path:
User-agent: *
Disallow: /search/
This asks matching crawlers not to crawl URLs under /search/. However, if those URLs contain valuable content that search engines need to discover, the rule may be inappropriate.
3. Add Your XML Sitemap
If your website has an XML sitemap, include its full URL in the robots.txt file.
Sitemap: https://example.com/sitemap.xmlA sitemap helps search engines discover important URLs. Listing it in robots.txt provides an additional way to communicate its location, although search engines may also discover the sitemap through other methods.
4. Generate the File
Once you have selected the appropriate settings, the generator produces the robots.txt content. Depending on the tool, you may be able to copy the text, download a file, or make additional changes before publishing it.
5. Upload and Test the File
The robots.txt file should normally be available at the root of the relevant website host, such as:
https://example.com/robots.txt
After uploading the file, visit the URL in your browser to confirm that it is accessible and contains the intended rules. Then test important URLs using available crawler-testing tools and review the website’s technical SEO setup.
A generated file should never be published without checking whether it accidentally blocks important pages, images, scripts, or other resources.
Why Is a Robots.txt Generator Important for SEO?
A robots.txt generator can support technical SEO by making crawling instructions easier to create, review, and maintain. Although the file does not directly guarantee better rankings, appropriate crawling rules can help search engines access the content you want them to discover.
1. Helps Manage Search Engine Crawling
Websites can contain thousands of URLs, including administrative paths, internal search pages, duplicate variations, and other areas that may not need to be crawled frequently. A robots.txt file can discourage crawling of selected paths when doing so is appropriate.
For large websites, this can help manage crawler activity and reduce unnecessary requests to certain sections.
However, blocking a URL does not necessarily remove it from Google’s index. Search engines may index a URL without crawling its content if they discover it through external links or other signals.
2. Reduces Manual Configuration Errors
Writing robots.txt rules manually is not especially difficult, but mistakes can have significant consequences. A misplaced wildcard or an overly broad Disallow directive may prevent crawlers from accessing important website sections.
A generator helps organize directives and makes the initial configuration process easier. Nevertheless, not every generator understands your website’s SEO priorities, so manual review remains essential.
3. Supports Technical SEO Maintenance
Robots.txt rules may need to change when a website is redesigned, migrated, expanded, or restructured. A generator makes it easier to produce an updated configuration when new sections or crawling requirements arise.
Regular reviews help ensure that old development rules do not remain active on a live website.
4. Helps Identify Unnecessary Crawling
Some websites generate many URLs through filters, tracking parameters, internal search features, and sorting options. These URLs can create crawling challenges, especially when they produce large numbers of similar pages.
Robots.txt can be part of a broader strategy for managing crawler access. However, it should not be used automatically to block every parameterized URL. Some URL variations may contain valuable content, and search engines may need to crawl certain pages to understand their relationship to the rest of the website.
5. Makes SEO More Accessible to Beginners
Website owners do not always have the technical knowledge required to write crawler directives confidently. A robots.txt generator reduces the need to remember every syntax detail and makes the process more approachable.
This is particularly useful for bloggers, small businesses, content marketers, and people managing WordPress websites without a dedicated technical SEO team.
When Should You Use a Robots.txt Generator?
A robots.txt generator is useful whenever you need to create or revise crawler instructions. However, the need for one depends on the size, structure, and technical requirements of your website.
1. When Launching a New Website
A new website is an ideal time to review its robots.txt configuration. Development environments sometimes use rules that discourage search engine crawling while the website is being built.
If these restrictions remain after launch, search engines may be unable to crawl important pages.
Before publishing your website, verify that the live robots.txt file does not contain unintended blocking rules. A generator can help you prepare a clean configuration, but it should not be treated as a substitute for checking the live website.
2. When Managing a WordPress Website
WordPress websites can benefit from robots.txt planning, especially when they use multiple plugins, SEO tools, custom post types, or e-commerce functionality.
For example, website owners may want to review whether internal search URLs or certain administrative paths need crawling restrictions.
However, avoid blindly blocking WordPress directories such as /wp-content/. This directory can contain images, stylesheets, JavaScript files, and other resources that search engines may need to render pages correctly.
Also, WordPress installations can use a virtual robots.txt response when no physical file exists. If you create a physical file, confirm that the server is serving the intended version.
3. When Running an E-Commerce Website
Online stores often generate many URLs through product filters, sorting options, search results, and pagination. These variations may create crawling inefficiencies or duplicate-content challenges.
A robots.txt generator can help create rules for specific URL patterns when restricting crawling is appropriate.
Before blocking product filters or other URL patterns, analyze whether they lead to valuable landing pages, unique product collections, or content that should remain discoverable. A rule that saves crawling resources in one situation may hide useful content in another.
4. When Managing a Large Website
Large publishers, marketplaces, directories, and SaaS websites may have complex URL structures and substantial crawling requirements.
A robots.txt generator can help organize crawler-specific rules and reduce the effort required to maintain them.
For very large websites, robots.txt should be part of a wider technical SEO strategy that includes XML sitemaps, canonical tags, internal linking, server logs, crawl analysis, and indexation monitoring.
5. When Updating Your Website Structure
Website redesigns, URL changes, migrations, and new content sections can make existing robots.txt rules outdated.
For example, an old rule may refer to a directory that no longer exists, or a newly launched resource section may be unintentionally blocked.
Use a generator when revising your rules, then compare the updated file with the previous version and test important URLs before and after deployment.
6. When You Need Different Rules for Different Crawlers
Robots.txt supports user-agent groups, allowing website owners to specify different crawling instructions for different crawlers.
For example:
User-agent: Googlebot
Disallow: /temporary/

User-agent: *
Disallow: /internal-search/
This example requests that Googlebot avoid /temporary/, while the general rule requests that other matching crawlers avoid /internal-search/.
Actual behavior depends on crawler-specific interpretation and rule selection. If you need different behavior for a particular search engine or other crawler, check its official documentation before publishing the configuration.
Important Robots.txt Directives You Should Know
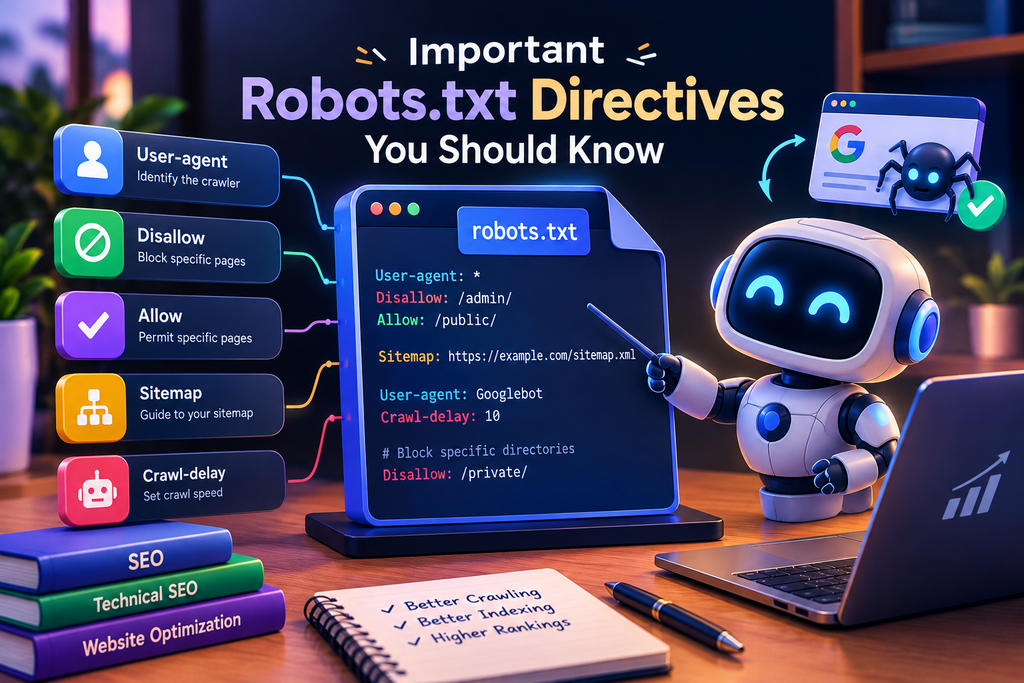
Understanding common directives helps you use a robots.txt generator more effectively.
User-agent
The User-agent directive identifies the crawler to which a group of rules applies.
Example:
User-agent: *The asterisk represents all matching user-agents. You can also specify a recognized crawler name, such as Googlebot, when you need crawler-specific instructions.
Disallow
The Disallow directive requests that matching crawlers not crawl a specified path.
Example:
User-agent: *
Disallow: /private-area/
This rule does not provide access protection. If the path contains confidential information, use authentication or appropriate server-side access controls instead.
Allow
The Allow directive explicitly permits crawling of a path. Some crawlers, including Google, support it alongside Disallow and use the most specific matching rule when resolving conflicts.
Example:
User-agent: *
Disallow: /resources/
Allow: /resources/public-guide/
This example is intended to permit crawling of the public-guide path even though the broader resources path is disallowed. Test the exact URL patterns before using such rules.
Sitemap
The Sitemap directive identifies the location of an XML sitemap.
Example:
Sitemap: https://example.com/sitemap.xmlA sitemap can help search engines discover canonical URLs that you want them to consider for indexing. Include the actual sitemap URL for your website rather than copying the example.
Wildcards and End-of-URL Matching
Some major crawlers, including Google, support wildcard matching using * and an end-of-URL marker using $.
For example:
User-agent: *
Disallow: /*?sort=
This rule is intended to match paths containing a query string that begins with sort= after the question mark. URL matching can be subtle, so confirm the intended behavior with the documentation and testing tools for your target crawler.
Not all crawlers support every extension in the same way.
Robots.txt Generator vs. Manual Robots.txt Creation
Website owners can create robots.txt manually using a text editor or use an online generator. Both approaches can work when the rules are correctly written and tested.
A generator is generally helpful for beginners who need a convenient way to prepare a standard file. It can reduce the need to remember syntax and makes it easier to build a configuration from selected options.
Manual creation, on the other hand, provides direct control over every directive. It can be useful for experienced developers and technical SEO specialists managing complex crawling requirements.
The most important difference is not whether a generator or a text editor is used. It is whether the final file accurately reflects the website’s crawling strategy.
A generated file can still contain harmful rules, while a carefully written manual file can be entirely valid. For this reason, use whichever method fits your workflow, and always test the result before publishing it.
Common Robots.txt Mistakes to Avoid
Even a simple robots.txt file can cause SEO problems when configured incorrectly. Understanding the most common mistakes can help protect your website’s crawlability.
1. Blocking the Entire Website
One of the most serious mistakes is publishing a rule that blocks all crawling:
User-agent: *
Disallow: /
This requests that all matching crawlers avoid the entire website. It may be appropriate for a private staging environment, but it is generally unsuitable for a public website that should be crawled.
Always inspect the live file after deployment.
2. Treating Robots.txt as a Noindex Directive
Robots.txt is not a reliable way to remove a page from search results. A blocked URL can still appear in search results if search engines discover it elsewhere.
If you need a page to be excluded from Google’s index, use an appropriate indexing control, such as a noindex meta tag or an X-Robots-Tag HTTP header, and ensure Google can crawl the page to see that instruction.
Blocking the page in robots.txt may prevent Google from seeing the noindex instruction.
3. Blocking Important CSS and JavaScript Files
Search engines may need access to resources that help them render a page correctly. Blocking important CSS or JavaScript files can interfere with their understanding of the page’s content and layout.
Before disallowing resource directories, verify whether they contain files required for rendering.
4. Assuming Disallow Protects Confidential Information
Robots.txt instructions are publicly accessible, and compliant crawlers may choose to follow them. Malicious crawlers can ignore them entirely.
Never use robots.txt to protect passwords, customer records, confidential documents, or restricted business information. Use proper authentication, authorization, and server-side security controls.
5. Forgetting to Update the Sitemap URL
An outdated sitemap reference can make your robots.txt configuration less useful. If your XML sitemap location changes, update the relevant directive and confirm that the sitemap is accessible.
6. Failing to Test Changes
A file that looks correct at first glance may still contain unintended matching patterns.
Test representative URLs, inspect important pages, and monitor crawling behavior after making significant changes. For larger websites, consider using crawler software and server logs to identify unexpected restrictions.
How to Create a Robots.txt File Using a Generator
Creating a robots.txt file is straightforward when you follow a structured process.
Step 1: Choose a reliable generator. Select a tool that allows you to create standard directives and review the generated text before downloading or publishing it.
Step 2: Review your website structure. Identify the directories and URL patterns that should be crawled, along with any paths that may need restrictions.
Step 3: Add only necessary restrictions. Do not block a path simply because its name sounds technical or administrative. Determine whether crawlers need access to it.
Step 4: Include your sitemap location. Add the correct XML sitemap URL if one is available.
Step 5: Generate and review the file. Check the syntax, spelling, path patterns, and crawler groups. Pay particular attention to broad rules and wildcard characters.
Step 6: Upload the file to the website root. Place the file where it can be accessed through the appropriate host’s /robots.txt URL. Ensure that the server returns the expected content.
Step 7: Test the configuration. Use relevant search engine testing tools or a crawler to confirm that important URLs are not blocked accidentally.
Step 8: Monitor your website. Review crawling reports, indexing signals, and technical SEO data after implementation. Revisit the configuration whenever the website structure changes.
Following these steps makes robots.txt management more predictable and helps reduce the chance of accidental crawling restrictions.
Best Practices for Robots.txt Optimization
A good robots.txt configuration should be simple, purposeful, and easy to maintain. Use the following best practices when creating or updating your file.
- Keep rules specific: Avoid broad restrictions unless you understand their full impact.
- Protect important content: Ensure that valuable pages and resources remain crawlable when search engines need access to them.
- Use XML sitemaps: Identify your sitemap location to support URL discovery.
- Review crawler documentation: Different crawlers may interpret some directives differently.
- Separate crawling from indexing: Use appropriate indexing directives when your goal is to prevent a page from appearing in search results.
- Protect private data correctly: Use authentication and server-side permissions rather than relying on robots.txt.
- Check after website updates: Revisit the file after migrations, redesigns, and major URL changes.
- Maintain a backup: Keep a copy of the previous version so you can compare changes and restore a working configuration if necessary.
- Test before deployment: Verify that critical landing pages, product pages, blog posts, and important resources are not unintentionally blocked.
These practices help make robots.txt a useful part of a broader technical SEO workflow rather than a file that is created once and forgotten.
How Does Robots.txt Affect Search Engine Indexing?
Robots.txt and search engine indexing are closely related, but they serve different purposes.
Crawling is the process through which a search engine accesses a URL and retrieves its content. Indexing involves analyzing and potentially storing that content so it can appear in search results.
Robots.txt primarily influences crawling. When a search engine follows a disallow rule, it may not retrieve the page’s content. However, the URL may still be indexed if the search engine discovers it through links or other signals.
If a page should not appear in search results, the correct solution depends on the page’s purpose. A noindex directive can help prevent indexing when the crawler is allowed to access the page and see that directive. If the content is confidential, access controls are required.
For effective SEO, website owners should manage crawling and indexing as separate but coordinated processes.
How to Choose the Right Robots.txt Generator
Not every robots.txt generator offers the same functionality. Before choosing a tool, consider whether it supports the features required by your website.
Ease of Use
A good generator should have a straightforward interface that allows you to create rules without unnecessary complexity. Clear descriptions of directives can be particularly helpful for beginners.
Custom Rule Support
Choose a generator that allows you to specify custom paths, crawler names, and sitemap locations. This flexibility is useful when your website has a unique structure.
Preview and Download Options
The ability to review generated text before publishing it helps you identify mistakes. Download options can also simplify uploading the file to your server or website management platform.
Validation Features
Some tools provide syntax checks or testing features. These can help identify formatting problems, although you should still verify how your target crawlers interpret the rules.
Compatibility With Your Website Platform
If you use WordPress, an e-commerce platform, or a custom content management system, ensure that you understand how the platform handles robots.txt. Some platforms generate the file dynamically, while others allow you to upload a physical file.
The right generator should simplify your workflow without hiding the actual directives from you.
Frequently Asked Questions About Robots.txt Generators
What is a robots.txt generator used for?
A robots.txt generator creates a text file containing instructions about which website paths participating crawlers should or should not crawl. It helps website owners manage crawler access and maintain their technical SEO configuration.
Is a robots.txt generator free?
Many online robots.txt generators are available for free. They generally provide basic features for creating and downloading a file. More advanced SEO platforms may offer additional auditing, validation, or crawling tools as part of paid services.
Does robots.txt improve Google rankings?
A robots.txt file does not directly guarantee higher rankings. Correctly managing crawling can support technical SEO, but rankings depend on many factors, including content relevance, page quality, site architecture, competition, and other search systems.
Can I create a robots.txt file without a generator?
Yes. You can create a plain-text file named robots.txt using a text editor. Write the required directives, save the file as plain text, upload it to the appropriate website root, and test the result.
Where should the robots.txt file be located?
For a typical website, the file should be available at the root of the relevant host, such as https://example.com/robots.txt. Different subdomains have their own robots.txt locations, and HTTP and HTTPS hosts should be checked according to how your website is configured.
Should every website have a robots.txt file?
Not every website requires special crawling restrictions. A robots.txt file can still be useful for communicating a sitemap location or defining specific crawling rules. If no restrictions are necessary, avoid adding unnecessary directives that could cause problems.
Does robots.txt block a page from Google search results?
Not reliably. Robots.txt primarily controls crawling, not indexing. A blocked URL may still appear in search results if Google discovers it through other sources. Use an appropriate noindex directive when indexing prevention is the goal and the page can be crawled, or implement access controls when the content must remain private.
Can robots.txt block AI crawlers?
Some crawlers used by AI services may honor robots.txt directives, but behavior varies by crawler and service. Identify the specific crawler and consult its documentation before creating rules. Robots.txt is a request to compliant crawlers, not a technical enforcement mechanism.
Conclusion
A robots.txt generator is a practical tool for creating and maintaining the crawler instructions used in technical SEO. It helps website owners generate directives, manage selected crawling restrictions, identify sitemap locations, and reduce common configuration mistakes.
It is especially useful when launching a new website, managing a WordPress installation, operating a large e-commerce store, or updating an existing website’s URL structure. However, generating the file is only one part of the process. You must also understand the difference between crawling and indexing, avoid blocking valuable resources, protect confidential information through proper security controls, and test the final configuration.
When used correctly, a robots.txt generator can simplify technical SEO maintenance and support a more organized approach to search engine crawling. The best results come from combining accurate robots.txt rules with high-quality content, clear site architecture, XML sitemaps, and regular technical SEO audits.

Leave a Reply